Author: Lincoln Wang | Founder & CEO, MindsLeap | Partner and CEO, Founders Space China | Founder, MindsLeap Founders AI Club
"The Hard Part Is Making Them Act Reliably"
Harrison Chase opened his latest LangChain talk with a blunt observation.
Over the past year, many organizations have learned how to ship AI agents. What separates leaders from followers is no longer who builds the prettier first version — it's who ships earlier and iterates with a systematic approach.
He said:
"The hardest part of building and shipping AI agents is making them act reliably."
That sentence deserves careful attention.
It means the competition around AI agents is shifting phases. Phase one is demos: get a model to call tools, open a webpage, write some code, complete a task that looks impressive. Phase two is production: the same AI agent must face hundreds, thousands, or even millions of real users and real business scenarios.
In phase one, surprise matters most.
In phase two, reliability matters most.
Harrison Chase is the co-founder and CEO of LangChain. Over the past few years, LangChain has been at the center of nearly every major evolution in AI application development — from chain calls to tool use, to LangGraph, LangSmith, and the full AI agent development stack. What he shared this time wasn't about a specific new feature. It was a deeper judgment: enterprises can no longer treat AI agents as one-off projects. They need to treat them as a new kind of worker that requires engineered operations.
Frameworks Aren't the Answer — Transparency Is
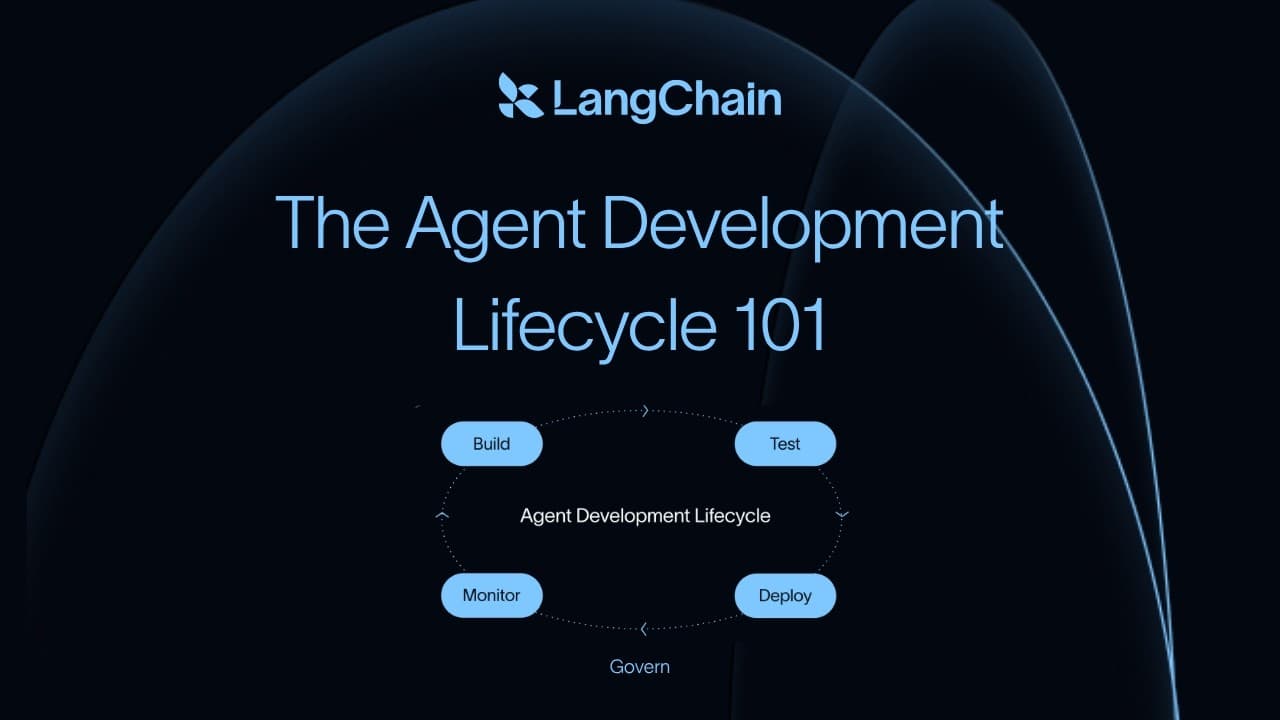
Harrison started with build.
Of course you can use frameworks to build AI agents. The value of frameworks is clear: they abstract model inputs, model outputs, tools, prompts, and retrieval, helping teams get started faster.
But he also shared an early LangChain lesson.
They once had a chain that secretly made five LLM calls under the hood. Users asked: "Why is this chain five times slower than calling OpenAI directly?" The answer was simple: the framework was making five calls underneath, and users didn't know.
This wasn't a small bug. It was a signal.
When AI applications enter production, what developers fear most isn't complexity — it's hidden complexity. A business leader sees "this AI agent is slow." An engineer sees "five model calls, three tool calls, two context concatenations." Without transparent tracing and clear structure in between, problems become black boxes.
So Harrison's attitude toward frameworks is nuanced: frameworks have value, but they must not hide what's actually happening.
This is especially important for enterprises. When many companies adopt AI tools, their first instinct is to find an all-in-one platform that wraps up all the complexity. But AI agents aren't traditional SaaS. Every execution can follow a different path based on context, tools, permissions, and user feedback. If you can't see its path, you can't manage its quality.
Not Writing Code — Defining a Working System
What's really interesting is Harrison's observation that AI agents are becoming less and less like code.
Prompts can be Markdown files. Tool connections can be MCP configurations. Skills can be a set of documentation and scripts. In many cases, an AI agent's "job description" is growing out of the codebase.
The implications behind this are significant.
In the past, enterprises built software by encoding processes into systems. Now, building AI agents is more like defining boundaries for a system that acts: what files it should read, what tools it can call, when it needs human approval, when it should stop.
Harrison mentioned a higher-level concept: harnesses. Many coding agents are essentially harnesses. They don't just call models — they manage context, file systems, human intervention, sub-agents, skills, and state across long-running tasks.
This reminds me of a common misconception in enterprises: people think an AI agent is "a model plus a few tools." But what Harrison is really describing is something else: an AI agent is a working system.
If you treat it as a tool, it can only answer questions.
If you treat it as a working system, it can actually own processes.
Testing AI Agents Is More Like Testing a Person Than a Model
Moving to test, Harrison made the differences even clearer.
Testing ordinary LLM applications is relatively simple — it's essentially calling a model in a loop. You might need to handle rate limiting, but overall it's not complex.
AI agents are different.
"When testing AI agents, each agent might run for fifteen minutes, thirty minutes. It doesn't just answer — it produces artifacts, it interacts with the environment."
This is key.
Traditional software testing often means inputting a value and checking an output. Testing AI agents is more like assigning a task to an employee and checking whether they actually got it done.
Harrison cited the example of coding agent benchmarks. You can't just look at which files it changed — you need to run unit tests and verify whether the results hold. This is criteria-based judging: it's not about whether the process looks pretty, but whether the outcome passes.
The bigger challenge is that AI agents in real business often have no standard answer.
Did a customer service AI agent handle a case appropriately? Did a sales AI agent advance an opportunity? Did an operations AI agent find an anomaly? These questions can't rely on ground truth alone. They need datasets, edge cases, evaluation criteria, and business experts to help define what "done well" means.
This is why I've always believed that AI transformation isn't about buying models — it's about restructuring organizational capability. What enterprises really lack isn't people who can write prompts, but people who can translate business judgment into evaluation standards.
After Deployment, the Problems Become Real
When Harrison discussed deploy, what he listed wasn't "how to go live" — it was a string of real-world problems.
If an AI agent fails halfway through, can it resume from where it stopped, or must it start over?
Does it have short-term and long-term memory?
Should what it returns to users be just tokens, or should it also include thinking process, tool calls, and execution status?
How does human approval fit into the workflow?
If an AI agent writes and executes its own code, where should that untrusted code run?
These questions sound engineering-focused, but they're fundamentally management questions.
An AI agent running once in a local demo — you can pretend none of these issues exist. But once it starts connecting to Notion, CRM, ticketing systems, financial systems, once it starts calling tools on behalf of employees or the organization, it's no longer a chatbot. It's a digital worker with partial agency.
Harrison noted that human-in-the-loop is easy locally but hard at production scale. How do you pause an AI agent, wait for approval, then continue? Which tools require approval? Which actions can be automated?
This is the watershed moment for enterprise AI adoption.
Truly mature AI-native organizations don't automate everything. They know very clearly: what must be automated, what must pause, and what must leave an audit trail.
If You Can't See the Traces, You Can't Govern AI Agents
Harrison said something simple in the monitoring section: monitoring tells you what the AI agent actually did.
The most fundamental piece is tracing.
"This is probably the most basic thing you should set up before entering production."
It needs to record every step the AI agent takes: what was the input at each step, what was the output, which tools were called, what did sub-agents do, what context did the LLM see.
This isn't for show — it's for debugging.
Harrison said most AI agent failures happen because the LLM didn't get the right context. So whether you can see what it saw at that moment becomes the core of troubleshooting.
Beyond that, you need to find the truly important signals from thousands of traces. User likes, dislikes, feedback — even users saying "you got it wrong" or "you should have done X instead of Y" — all become signals. LangChain calls these perceived errors: judging whether the AI agent made mistakes from the traces of human-AI agent interaction.
This is critically important for enterprises.
Because in the future, managing AI agents can't rely on bosses opening ten chat logs every day for manual inspection. You need dashboards, online evaluations, and mechanisms that automatically cluster problems. Otherwise, the more AI agents you have, the more out of control your organization becomes.
Governance Isn't the Last Step — It Wraps the Entire Lifecycle
Finally, Harrison discussed govern.
Many people assume governance is a compliance action after going live. But in his framework, governance isn't a separate phase — it wraps the entire lifecycle of build, test, deploy, and monitor.
Cost control is one part. LangChain itself is heavily using coding agents internally, and Harrison said costs have become somewhat out of control, so they need to see costs and manage them.
Tool permissions are another part.
"When an AI agent uses Notion, is it acting on my behalf, a colleague's behalf, or a service account?"
This sentence immediately brings the problem back from technology to organization.
When an AI agent calls tools, it's not just an API permission issue — it's a question of accountability. Who authorized it? Who bears the consequences? Who can audit it? Which tool calls require human-in-the-loop? Which contexts and skills can be shared?
Once enterprises truly deploy AI agents, all these questions become daily management issues.
So what's truly valuable about this talk isn't telling us what new products LangChain has built. It's a judgment: the productionization of AI agents is forcing enterprises to reinvent a hybrid system of software engineering and organizational governance.
In Closing: From "Can Do" to "Can Manage"
Many enterprises today are still stuck on the first-level question: Can AI agents help me write reports, look up information, run processes?
Harrison Chase's talk reminds us that the real question has moved forward: when AI agents actually start working, can you continuously improve them? Can you test them? Can you see what they did? Can you bring humans in before critical actions? Can you control costs, permissions, and audits?
This is the distance from demo to production.
Demos prove model capability.
Production tests organizational capability.
For Chinese entrepreneurs, this may be the most important dividing line to seriously understand this year: an AI agent isn't a tool you "deploy and done." It's a new organizational unit. It needs job descriptions, probation periods, performance reviews, permission boundaries, and continuous training and retrospectives.
The gap between enterprises in the future isn't just about whether they have AI agents — it's about who can integrate AI agents into their management systems.
When the demo ends, the real work has just begun.
About MindsLeap
MindsLeap is an AI-native organization transformation accelerator.
We work closely with Founders Space, a Silicon Valley innovation incubator, to connect global AI frontier insights, Silicon Valley tech entrepreneurship ecosystems, and real transformation scenarios for Chinese entrepreneurs.
Around AI-native organization building, MindsLeap is building a transformation ecosystem for entrepreneurs, startup founders, AI engineers, industry experts, and investors — helping enterprises move AI from cognition, strategy, and tools into real organizational capabilities, business processes, product innovation, and growth systems.
This article was translated and adapted from the Chinese original with AI assistance.